A local AI setup gives you more control over the model and the machine it runs on. It also gives you a machine to maintain.
That tradeoff gets lost when businesses compare a hardware purchase with a monthly AI subscription. The hardware price is visible. So is the subscription bill. The work required to keep either option useful can be harder to estimate.
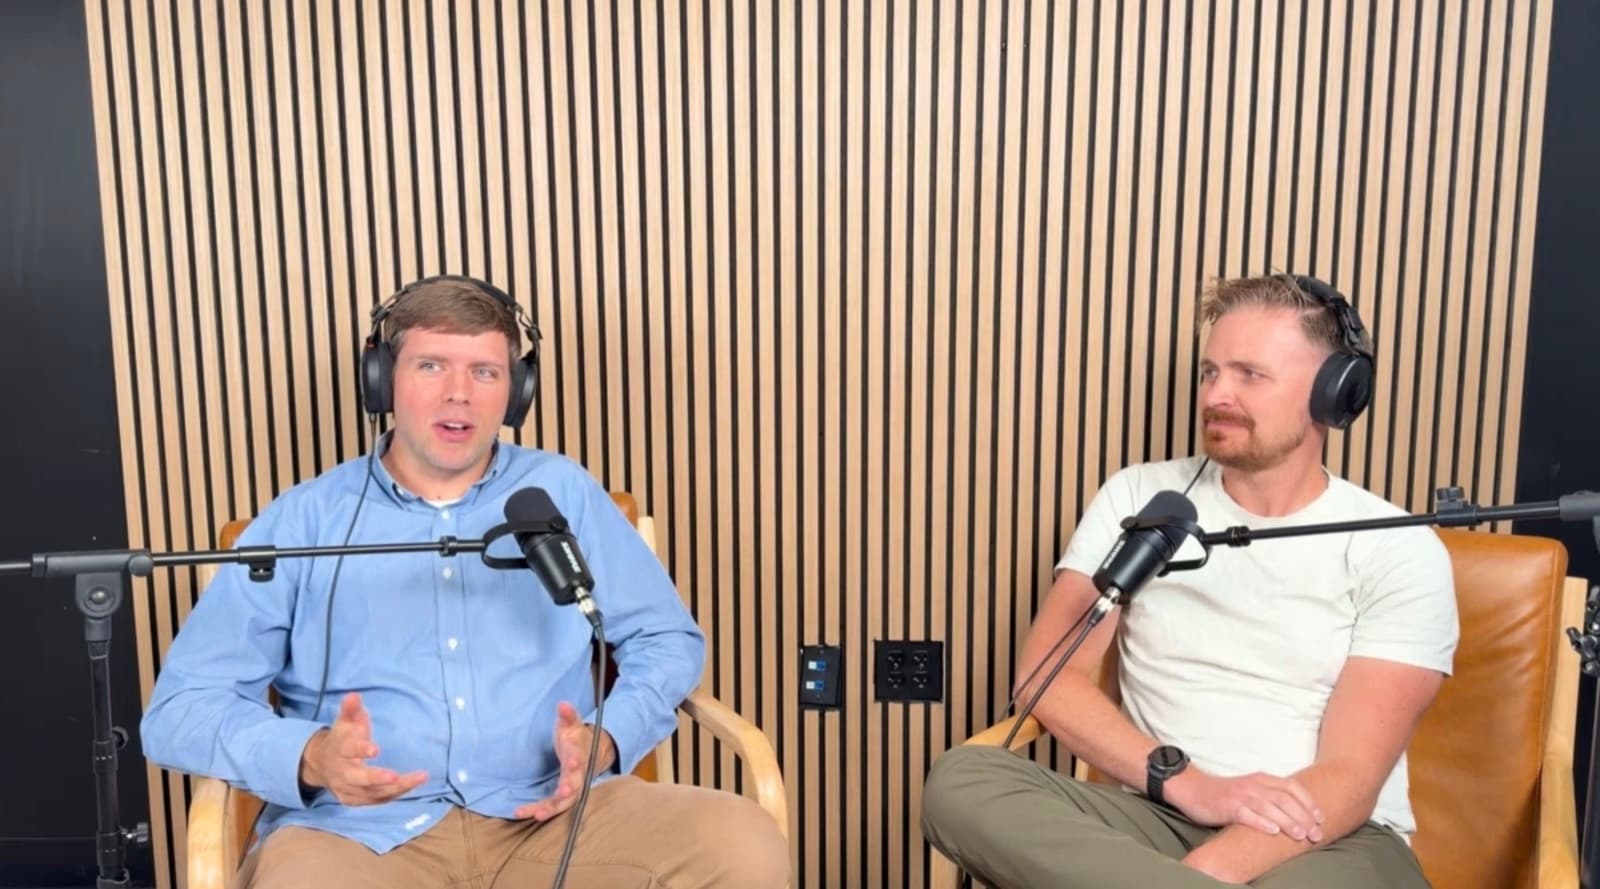
In Episode 4 of Where AI Fits, SageCreek AI’s Bob Bodily talks with Tyler Folkman, Chief AI Officer at JobNimbus, about running AI locally and putting it to work inside a company. Folkman is enthusiastic about his own local setup. He also makes a clear distinction between maintaining a personal system and supporting a business that needs dependable service.
For leaders considering local versus cloud AI, the conversation offers a useful starting point: decide what the business needs to accomplish before choosing the infrastructure.
Start with the workflow you want to improve
When Bodily asks how a company should organize for AI transformation, Folkman brings the discussion back to why the company wants to change. Is it moving too slowly? Struggling to grow? Losing ground to competitors?
“Know why, and then have some idea of how to measure that,” Folkman says. That principle gives the infrastructure decision a business purpose.
Those answers affect which workflows deserve attention and how an improvement should be measured. They also affect the infrastructure decision.
An assistant drafting an internal weekly update has different requirements from a customer-facing application handling confidential records. The first may tolerate a delay and a human rewriting the output. The second may need tight access controls, predictable availability, and a support plan.
Write down the workflow before comparing models. Identify its inputs, who uses the output, and what happens when the system fails. Establish the current cost and quality of the work, including the time people spend reviewing it. (For a step-by-step method, see how to find the right AI use case.)
That gives the team something more useful to test than a model’s reputation.
Where cloud AI can make sense
Folkman expects cloud AI to remain the easier choice for many people. A subscription or API removes much of the initial work of buying hardware and configuring a model runtime. It can also make it easier to try different models as a task changes.
Cloud appeals to many users because “it’s just a lot easier, it’s a lot simpler,” he says. That convenience matters when a team is still learning what it needs.
For a company exploring a new workflow, that can reduce the cost of learning. The team can test whether the output is useful before committing to infrastructure.
Cloud services still need review. The organization should understand the provider’s data handling terms, available retention controls, access permissions, usage limits, and reliability commitments. Those details vary by product and contract, which is why they belong in your AI governance process.
Usage also needs a budget. A workflow that seems inexpensive in a short demonstration can behave differently when more employees use it or an automated task retries repeatedly. Measure the cost of completing the actual task, including failed attempts and human correction.
Where local AI can be worth evaluating
Local AI means running a model on hardware under your control, such as a workstation or server. Folkman describes using his own setup for daily briefings, content work, and personal automations. Part of its appeal is the ability to keep using a particular model without depending entirely on a provider’s changing service.
Folkman describes the appeal as having “some amount of intelligence that you control.” For him, ownership creates options beyond the terms of a hosted service.
That control can matter when a workflow has specific data requirements, needs a stable configuration, or runs often enough to justify investigating different economics. Local models can also help technical teams understand how inference settings and surrounding software affect behavior.
The episode discusses several hardware approaches, including GPUs, Apple systems with unified memory, and compact NVIDIA systems. The practical question is whether the chosen hardware can run an adequate model at the speed and workload the task requires.
“The name of the game in local AI is you need to get enough memory,” Folkman explains. He also emphasizes how quickly the model can access that memory. Capacity alone does not tell a team whether a setup will be useful.
A buying decision needs more evidence than a list of model sizes. Test the actual work, with realistic inputs and enough simultaneous usage to expose bottlenecks.
Owning the hardware does not settle security or cost
A locally hosted model can reduce the information sent to an external inference service. That does not make the whole application private by default.
The application may still call search services, browse websites, write logs to another platform, or use a cloud fallback. Access to the machine and its backups also matters. The team needs to examine the complete data path, not only where inference runs.
Cost needs the same treatment. Local infrastructure brings electricity, administration, maintenance, and replacement costs. Business use may require monitoring and recovery arrangements that a personal setup can do without.
Folkman acknowledges this distinction. He can tolerate a personal system being temporarily unavailable. That is a different proposition from a company relying on the system to serve customers.
Enterprise use adds “this whole other cost,” he says, referring to stability and uptime. His personal tolerance for troubleshooting is not a service standard a business can assume its users will accept.
For cloud options, include integration and support alongside provider charges. For local options, include the people who keep the service running. Compare the total cost of an acceptable result, with the same quality standard on both sides.
Include the software around the model
Bodily and Folkman discuss the role of a model’s surrounding software, sometimes called its harness. Tools, context, and application logic help turn model output into completed work.
That matters when a company debates whether it needs a more capable model. A missing data connection or unclear approval step may be the bigger problem. Some parts of a workflow may be better handled by ordinary software rather than repeated model calls.
For example, an internal reporting assistant might use conventional code to retrieve approved records and calculate totals, then use AI to draft an explanation. A person can review the draft before it reaches a wider audience. This is an illustrative design, not a system described as deployed by JobNimbus.
The evaluation should cover the whole workflow. A fast model response has limited value if the employee spends longer finding missing context or checking unsupported statements afterward.
Support employee builders before their prototypes become dependencies
AI coding tools give more employees a way to solve their own problems. In the episode, Folkman describes the risk of those tools leading employees toward personal repositories and hosting accounts outside the company’s control.
Leaders should pay attention to the problem the employee is trying to solve. An improvised tool may point to a genuine gap in internal support, the same pattern behind shadow AI.
Give useful prototypes a route into company-owned systems. Name an owner, review the data and permissions, and decide how the tool will be maintained. Keep experiments away from sensitive information until the right controls are in place.
Folkman’s description of the ownership problem is concrete: employees can end up using “hosting that we don’t own.” A prototype’s usefulness does not remove the need to know where company information is going.
Also compare building with buying. Folkman points out that maintaining internally built software is still work, even when AI helps write it. An existing product may remain the better choice when the workflow is common and custom ownership adds little business value.
Choose after a bounded pilot
A company does not have to select one infrastructure model for every AI task. It can test an approved cloud service for one workflow, evaluate a local option for another, or compare both on the same task when the constraints allow it.
Set the success criteria before the pilot. Include output quality, total completion time, review effort, cost, and operational requirements. Record failures rather than removing them from the comparison. (Here is why so many AI pilots stall before they ship.)
If local inference meets the requirements and the company can support it, the additional control may be worthwhile. If a cloud service produces a better result within the organization’s data and budget requirements, buying hardware may add little value. A workflow can also fail the test entirely, which is useful to learn before scaling it.
At SageCreek AI, the starting point is identifying where AI can improve revenue, margin, or the work behind those outcomes. The infrastructure decision follows that work. You can see what that looks like in our case studies.
Take the AI Readiness Assessment or explore the AI opportunity audit process to decide which workflow deserves a closer look.